Attention Mechanism
The core idea Attention is a way of computing a weighted average where the weights themselves are learned. Given a set of items, the mechanism decides how much each one matters for the current purpos
Oct 13, 2026 · 5 min read
The core idea
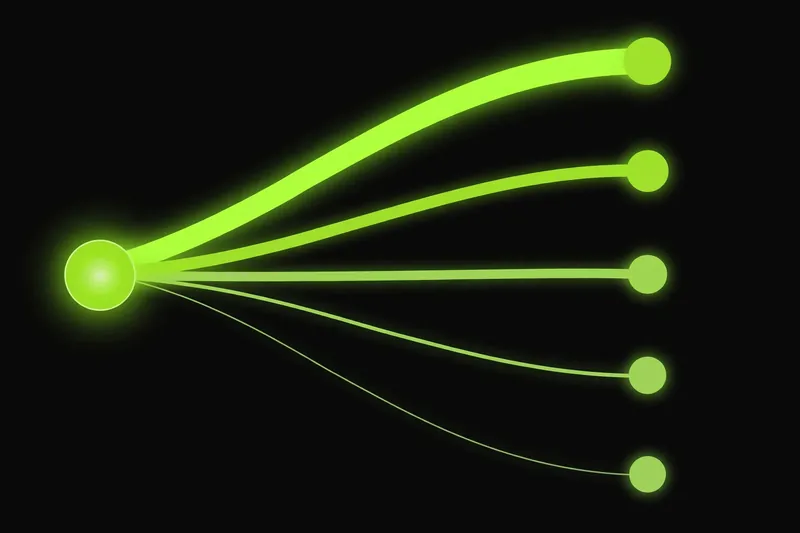
Attention is a way of computing a weighted average where the weights themselves are learned. Given a set of items, the mechanism decides how much each one matters for the current purpose, then blends them accordingly. The items that matter most dominate the mix. The rest fade into the background.
The standard framing uses three roles: queries, keys, and values. It helps to think of a database lookup. You issue a query, compare it against a set of keys, and retrieve the values attached to the best-matching keys. Attention does a soft version of this: instead of picking one winner, it assigns every key a weight based on how well it matches the query, then returns the weighted blend of all the values. Everything is differentiable, so the whole thing can be learned with gradient descent.
Where it came from
Attention entered neural networks through machine translation. In 2014, Bahdanau and colleagues added an attention mechanism to a translation system so that while generating each word of the translation, the model could look back at the relevant words of the source sentence instead of relying on a single compressed summary. Translation quality improved immediately, because the model no longer had to squeeze a whole sentence into one fixed-size vector.
The 2017 transformer paper took this further by making attention the primary computation rather than an add-on. Instead of using attention to connect an encoder and a decoder, it used self-attention inside each layer: every position in a sequence attending to every other position. That turned out to be enough to build entire models from.
Self-attention in detail
In self-attention, the queries, keys, and values all come from the same sequence. Each token asks, in effect: which other tokens are relevant to understanding me? For the sentence "The animal did not cross the street because it was too tired," a good model resolving the word "it" should attend strongly to "animal" and weakly to "street." The attention weights encode exactly these relationships, recomputed fresh for every input.
The computation is compact. Stack the queries into a matrix Q, the keys into K, the values into V, and:
```
Attention(Q, K, V) = softmax(QK^T / sqrt(d_k)) V
```
QK^T gives a score for every query-key pair. Dividing by the square root of the key dimension keeps the numbers in a range where softmax behaves well. The softmax turns each row of scores into weights summing to one. Multiplying by V blends the values by those weights. The output has one vector per query position, each one a context-aware mix of the whole sequence.
A small numeric example makes the mechanics concrete:
```python
import numpy as np
def softmax(x):
e = np.exp(x - x.max(axis=-1, keepdims=True))
return e / e.sum(axis=-1, keepdims=True)
# three token vectors; queries, keys, values are the same here
X = np.array([[1.0, 0.0],
[0.0, 1.0],
[1.0, 1.0]])
scores = X @ X.T / np.sqrt(X.shape[1])
weights = softmax(scores) # each row sums to 1
out = weights @ X # each output is a weighted mix of all inputs
```
The first token is most similar to itself and to the third token, so its output blends those two. Nothing here is learned; in a real model the Q, K, V projections are learned matrices, and the patterns they find are far richer.
Multi-head attention
One attention operation produces one set of weights per position. Multi-head attention runs several of these in parallel, each with its own learned projections, and concatenates their outputs. The original transformer used eight heads.
The motivation is that a single weighting cannot capture everything. In "The animal did not cross the street because it was too tired," one head might link "it" to "animal" while another tracks the negation in "did not." Researchers have found that heads do specialize, though often in ways that are harder to interpret than the textbook examples. Some heads track syntax, some track position, some seem to do little at all. The redundancy is part of why the architecture is forgiving.
Causal masking
When a model generates text, it produces one token at a time and must not peek at future tokens. Decoder self-attention enforces this with a causal mask: before the softmax, the scores for all future positions are set to negative infinity, which makes their weights zero. Each position can then only attend to itself and the past. This is what makes autoregressive generation work, and it is also what lets training process all positions in parallel while still learning a properly left-to-right model.
Cross-attention
In the original encoder-decoder transformer, the decoder layers also attend to the encoder's output. Here the queries come from the decoder's positions while the keys and values come from the encoder. This lets each generated word pull in the relevant parts of the input. Cross-attention survives in translation and in systems that condition generation on something else, like an image or an audio clip, where the queries come from the text being generated and the keys and values come from the other modality.
Costs and limits
Attention's strength is also its expense. Every position compares against every other, so compute and memory grow with the square of the sequence length. Doubling the input length quadruples the attention cost. This quadratic scaling is the main reason context windows are capped, and it has driven a long line of research into cheaper approximations: sparse patterns that skip most pairs, linear variants that reformulate the computation, and sliding windows that restrict how far back each position can look.
Attention weights are sometimes described as showing what the model is "thinking." That reading needs care. The weights show which inputs influenced a given output vector, but the values being mixed and the layers above also shape the result. High attention weight on a token does not always mean the token caused the decision. The weights are a useful diagnostic, not a full explanation.
Comments
Loading comments…